Online · 2026-09-16 · 08:00–09:00 PT
Talk Title: Building Reliable Evaluations for Frontier Agents
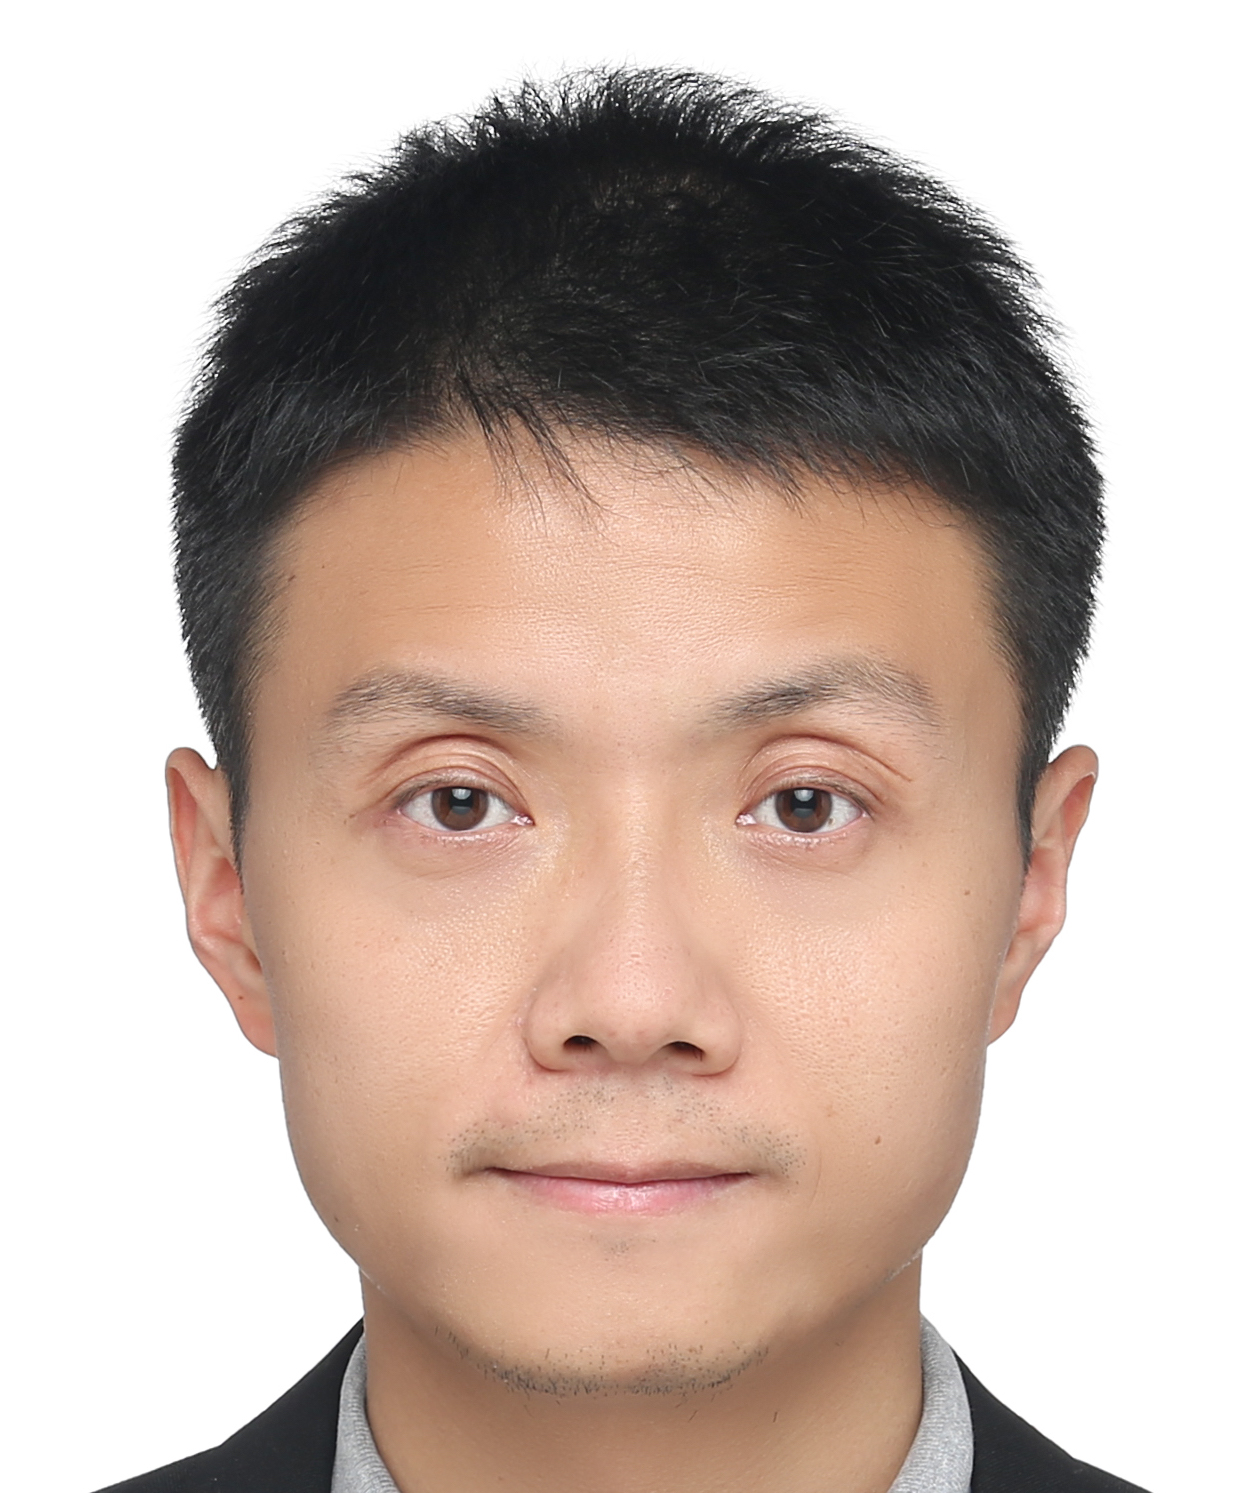
Research Scientist · Daniel Zhang · Scale AI
As frontier agents tackle increasingly complex, real-world work, the grading systems that evaluate their performance are now doing double duty-serving as both reinforcement learning rewards and mechanisms for test-time selection. This talk explores how Scale AI builds robust evaluations for cutting-edge coding agents and beyond, featuring insights from building leading leaderboards such as SWE-Bench Pro, SWE Atlas, Terminal-Bench, and MCP Atlas. It also examines the critical challenges of designing reliable verifiers, comparing programmatic versus rubric-based grading, identifying and mitigating reward hacking, and architecting agentic verifiers capable of auditing long-horizon tasks.
Bio: Daniel Zhang is currently Head of Agents Research at Scale AI, where his team focuses on frontier agent research in Coding, Computer Use, Long-horizon Tool Use, and Safety. Previously, he served as Post-training Lead at Amazon AGI, where he worked on reasoning and coding agents. He holds a Ph.D. in Computer Science from the University of Notre Dame and an M.S. in Information Security from Purdue University.